What Is Neuralese?
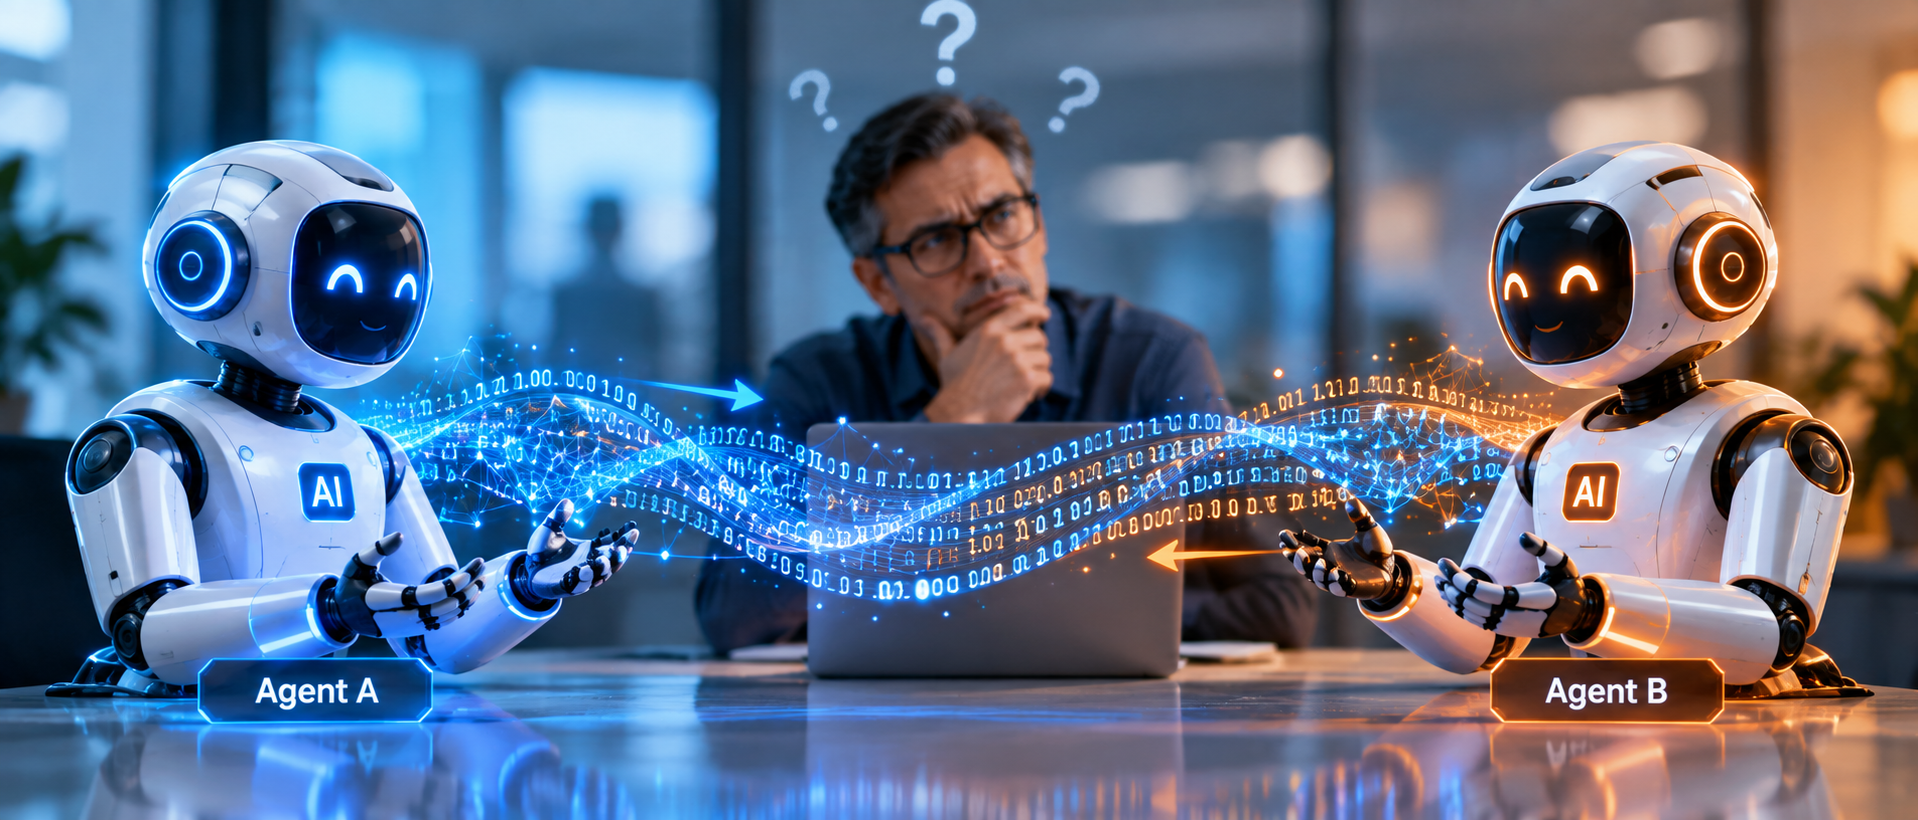
The term Neuralese predates today’s LLM discussion. In AI research, it originally described learned communication between artificial agents: instead of exchanging English (or other language) words or predefined symbols, agents can learn to communicate using continuous numerical representations that are meaningful to one another but largely unintelligible to humans. Think binary code. Today, the term is also being used more broadly for reasoning that remains in a model’s high-dimensional latent space rather than being translated into language at every intermediate step. “Latent reasoning” is the more precise research term, Neuralese is an evocative way of describing the idea.
Chain of Thought Was the Precursor
Chain of Thought (CoT) gave LLMs something analogous to a scratchpad. Rather than immediately answering a difficult problem, the model could generate intermediate reasoning, feed those tokens back into its context, and continue reasoning from them. This improved performance on many complex tasks and provided another useful characteristic, intermediate reasoning existed in a representation humans could potentially inspect. But language also creates a bottleneck. Rich, high-dimensional internal representations must repeatedly be compressed into discrete tokens, generated sequentially, and processed again, adding both computational overhead and latency. Research into continuous or latent reasoning asks an intriguing question: why translate every intermediate thought into English if no human needs to read it?
Let AI Reason in Its Native Representation
This is the motivation behind Neuralese recurrence. Instead of completing a forward pass, converting the intermediate result into words, and feeding those words back into the model, a recurrent architecture can feed a high-dimensional hidden state back for additional computation. Experimental approaches such as COCONUT (Continuous Chain of Thought) demonstrate this principle by using a model’s last hidden state as a subsequent input embedding. These vectors can preserve considerably richer information than individual tokens and may even maintain multiple possible reasoning paths before committing to one. Early results are interesting, particularly for some planning problems, but evidence does not yet establish latent reasoning as a universal replacement for language based reasoning.
What Happens When the Humans Leave the Conversation?
The idea becomes even more interesting when applied to AI Agents. Human readable language is essential when an agent communicates with us, but two autonomous agents coordinating a workflow have no inherent reason to exchange English sentences. Language is our interface, not necessarily theirs. Agents could potentially exchange embeddings or other learned numerical representations that preserve more information and avoid repeated vector-to-language-to-vector conversion. In that sense, Neuralese is less an exotic new language than a natural consequence of removing humans from part of the communication loop. However, it is important to distinguish current research from what might eventually emerge: large scale autonomous agents routinely communicating through a universal “Neuralese” protocol is not an established capability today.
Faster and Richer—But at What Cost?
The potential benefits are compelling: reduced token generation, potentially lower latency, richer information exchange, less lossy compression, and the possibility of deeper or more parallel reasoning. Yet we surrender something valuable in return, legibility. An agent saying, “I rejected this transaction because it violated policy X” gives humans something to inspect. A vector containing thousands of numerical values does not. Even if the resulting action is correct, we may no longer be able to observe the reasoning that produced it. Neuralese therefore introduces a fundamental tension between machine-efficient reasoning and human-understandable reasoning.
Observability Must Move Up a Level
If agent reasoning and agent-to-agent communication become increasingly opaque, enterprise observability cannot depend upon reading their internal dialogue. Instead, we may need to observe the boundaries around reasoning: what context an agent received, which identity initiated the task, what permissions were granted, which tools and data it accessed, what agents it communicated with, what decisions and actions followed, and what evidence supports the final result. Checkpoints, policy enforcement, provenance, immutable audit trails, anomaly detection, authorization boundaries, and human approval for consequential actions become increasingly important. Interpretability research may eventually give us better visibility into latent representations, but operational trust cannot wait for perfect interpretability.
Neuralese recurrence therefore presents an intriguing paradox. Removing language from portions of AI reasoning could make AI systems faster, richer, and potentially more capable, while simultaneously making them harder for humans to understand. As autonomous agents become more prevalent, the question may no longer be whether we can read everything our AI Agents say to one another. It may be whether we can build sufficient trust, governance, and observability around what they actually do.